Build the suite.
A set of questions and their known-correct answers, drawn from your model and how people really query it.
PRODUCT : semantic layer : CANARY (COMING SOON)
MEASURE AI ACCURACY
AtScale Canary tests AI answers against gold-standard SQL, using the BIRD-Interact benchmark method. If your LLM gets questions wrong, we use CoModel to fix it. Prompts that pass Canary become certified queries, marked as ready for automation and trusted human consumption.
THE PROBLEM
Data teams test pipelines, dashboards and code before they ship. AI answers usually get a spot check, with no measured error rate and no alert when a change breaks one. A wrong number that looks right gets used. Canary turns your business questions and known-correct SQL into a test suite and a score you can report.
how canary works
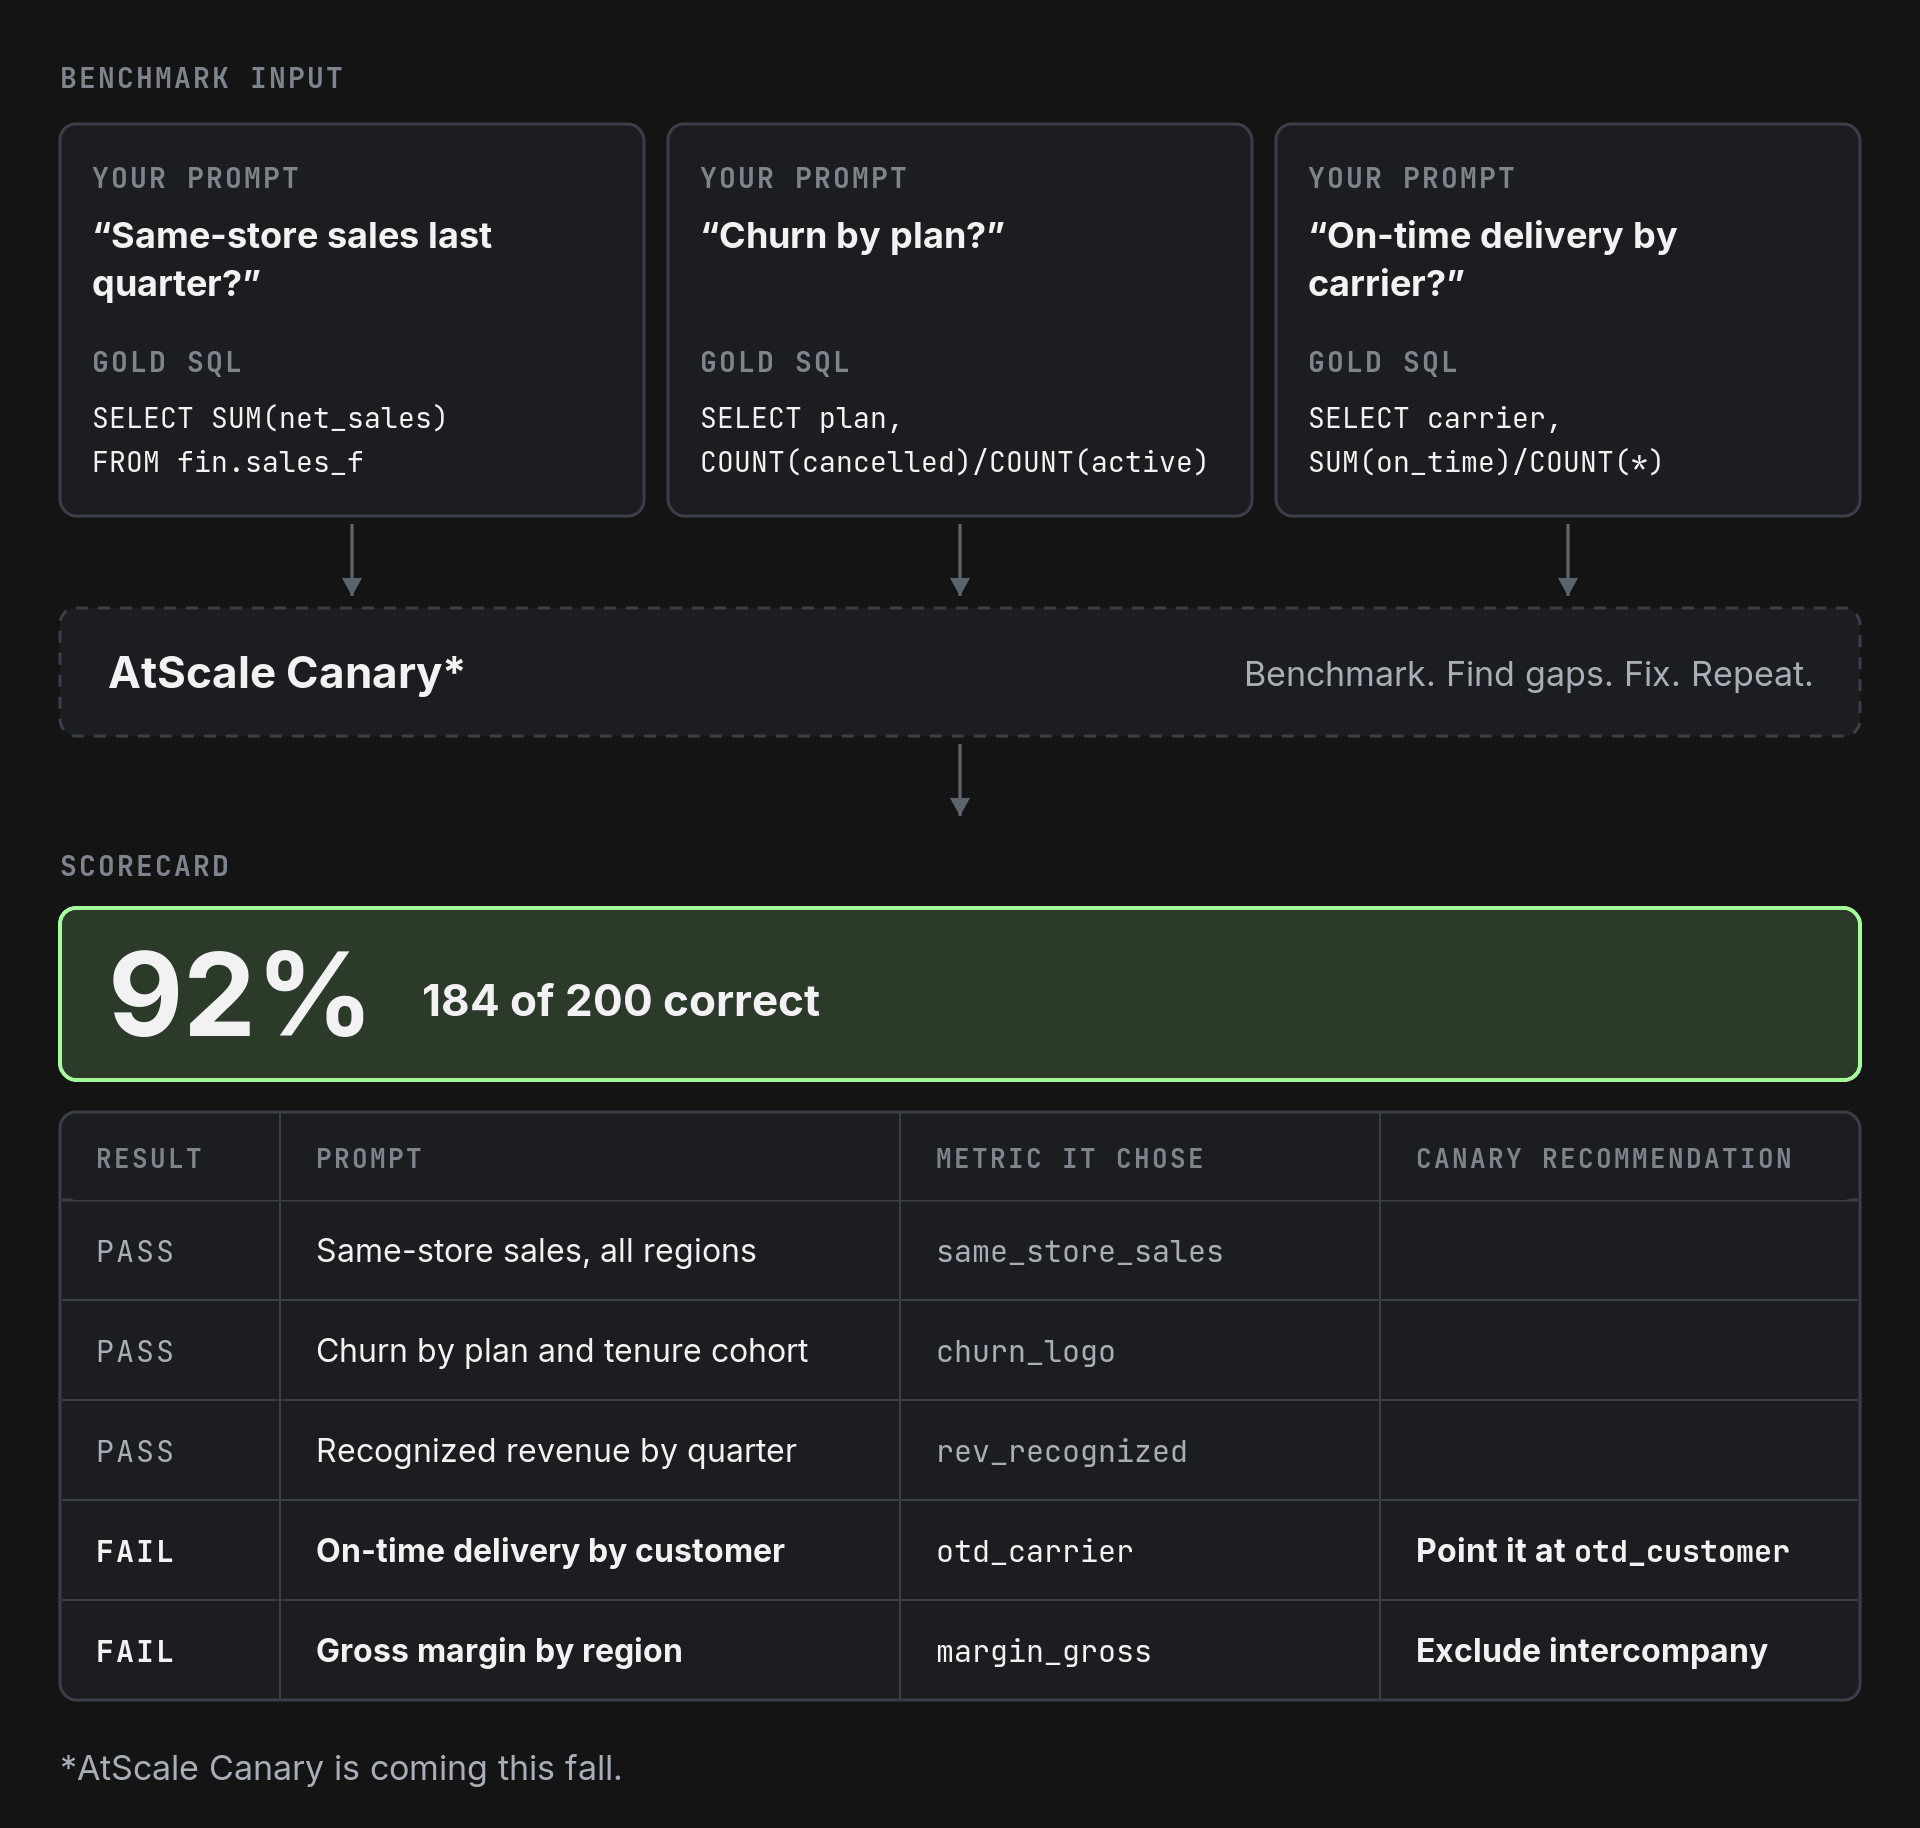
Canary runs each test prompt through a harness based on BIRD-Interact, compares the answer with the result of your gold SQL and records why mistakes were made. A simulated user answers Ava’s clarifying questions, so Canary scores ambiguous prompts too. It tests accuracy from prompt to computation, at every workflow stage.
WHAT IT DOES
List the questions your business asks. Each test case pairs a question with test data, the gold SQL and the validated result. Every test case passes or fails, and the goal is 100%.List the questions your business asks. Each test case pairs a question with test data, the gold SQL and the validated result. Every test case passes or fails, and the goal is 100%.
Canary runs every prompt and its gold SQL and reports a score, such as 184 of 200 correct.
Canary records why each answer missed, such as an ambiguous prompt or a missing metric definition, and what the model needs to fix it.
AtScale Semantic Modeling drafts the fix, Canary runs the suite again and a person approves the change. The test case stays in the suite, so you’ll catch it if the same miss comes back.
Run the suite on a schedule and before a launch or an audit. A falling score shows drift before it shows up in a board pack.
A set of questions and their known-correct answers, drawn from your model and how people really query it.
Canary runs the suite against your stack and scores every answer against the gold standard.
You get the failures and the reasons, plus a dated record you can hand an auditor or a regulator.
An agent doesn’t stop to sanity-check a number before it acts on it. Before an agent workflow goes live, turn the questions it’ll ask into Canary test cases. Promote only the model versions that pass, and run the suite again whenever the model or the agent’s LLM changes. Agents then call those attested metrics through the AtScale MCP server.
It compares the AI’s answer with the validated result of your gold SQL. Canary runs each test prompt through a harness based on BIRD-Interact, and every test case passes or fails.
Yes. A simulated user answers Ava’s clarifying questions during the run, so Canary scores ambiguous prompts too.
It’s known-correct SQL for a known question, written and reviewed by the people who own the metric.
A second model gives you another guess. Canary compares every answer with a result your team already knows is right.
Yes, and AtScale recommends starting there. A test case is a prompt, test data, gold SQL and a validated result. Public benchmarks such as BIRD-Interact can run alongside your own cases.
Canary records why the answer missed, such as an ambiguous prompt or a missing metric definition. AtScale Semantic Modeling drafts the fix, Canary reruns the suite and a person approves the change before it’s promoted.
Yes. Canary can score any answer, including answers from AI running without AtScale.
It’s a dated record of each prompt, the answer that came back, the correct result and the score. You can hand it to an auditor.
Yes. Canary compares your results against a baseline run without AtScale, so you can show what the semantic layer adds on your own questions.
Yes, with help from AtScale services at launch. You can query test results, and our services team connects your acceptance criteria to CI.
Yes. Turn the questions an agent will ask into Canary test cases and promote only the model versions that pass. Agents then call those attested metrics through the AtScale MCP server.